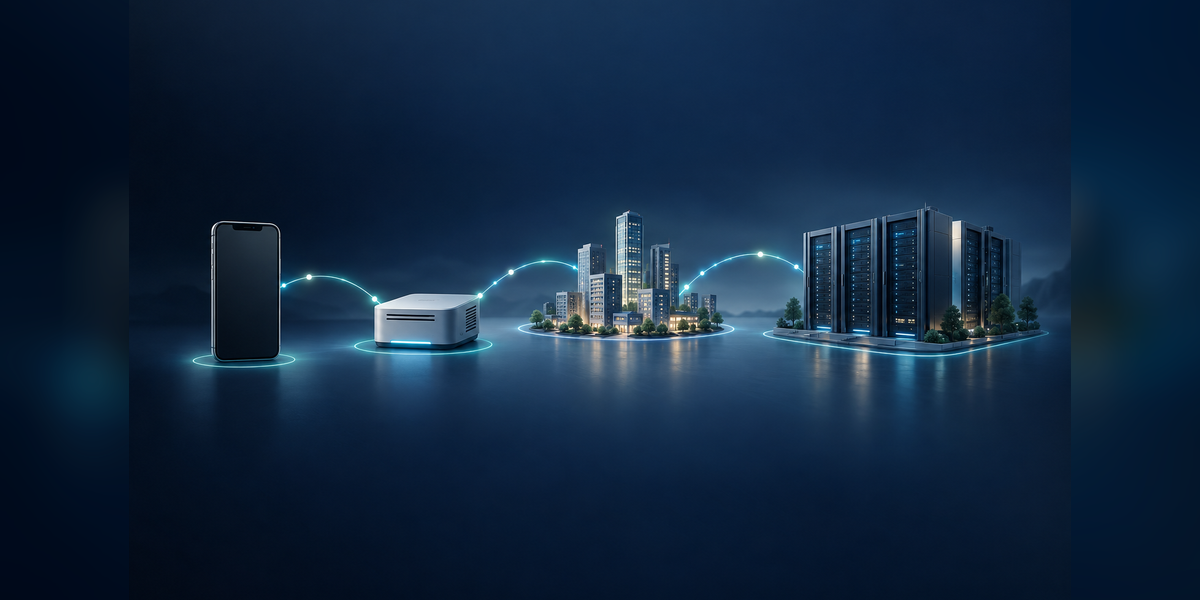
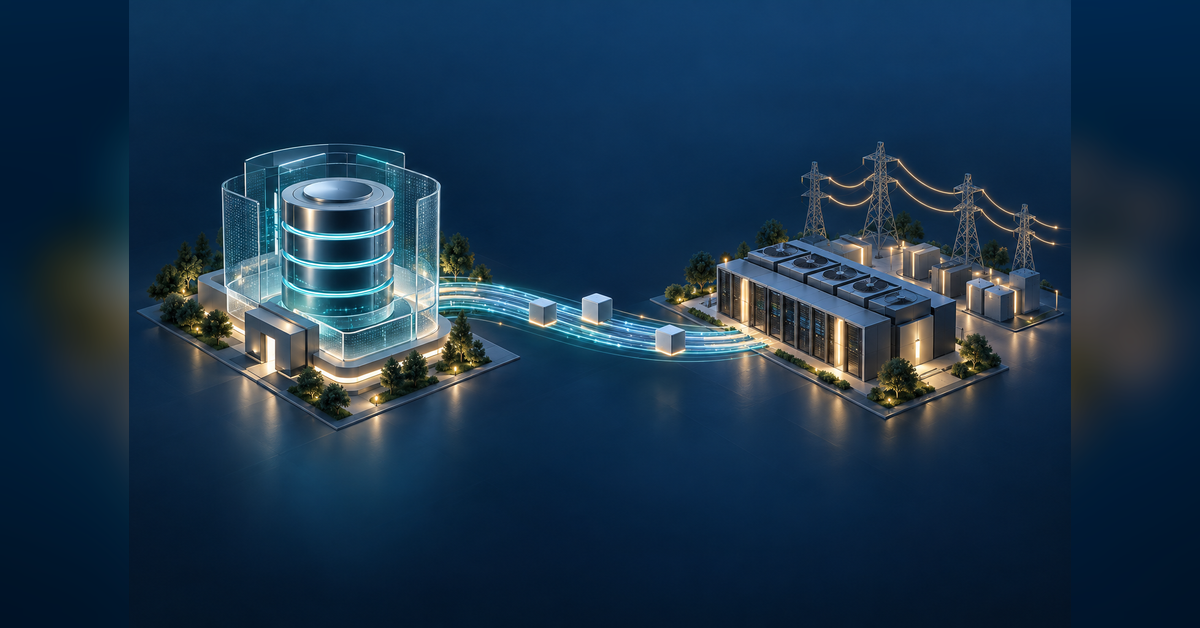

The data gravity AI buyers face is the architectural and economic pull that can make moving data less attractive than moving work to it. It competes with another pull: available GPUs, usable power and viable compute economics. Choose what moves by comparing constraints and the complete workload path, not dataset size alone.
This guide is for business owners and CEOs evaluating AI infrastructure, plus marketing leaders who need to explain the tradeoffs. The practical question is which information, processing and infrastructure should stay together, and which can be separated.
What is data gravity in AI?
Data gravity describes the architectural and economic reasons to locate processing near data rather than relocate the data. Treat it as a placement consideration, not a physical law, a fixed formula or a rule that data must always stay put.
Use the Dual Gravity Model to decide what moves
“AI infrastructure has two gravitational pulls: the data and the compute.”
Bob Generale, President of Percepture
Percepture’s Dual Gravity Model turns that tension into a decision aid. One side asks what makes the data difficult or undesirable to move. The other asks what makes a compute location worth considering despite that resistance.
- Set the boundaries. Identify restrictions on data movement, acceptable response times, security requirements and the delivery deadline. Separate documented constraints from preferences.
- Define the movable unit. Consider a complete dataset, an approved subset, a scheduled job, a model deployment or a processing stage. Do not assume the whole application must move together.
- Compare viable locations. Request evidence for GPU access, power, facilities, connectivity and the operating arrangement. Use the data center power availability guide to frame the power questions.
- Choose a test and a reversal trigger. Specify what the proposed arrangement must demonstrate and what would cause you to change it.
Do not assign a universal gravity score. Eliminate options that fail a documented requirement, then compare the remaining options on cost, performance, delivery and reversibility.
If placement is only one part of a larger investment decision, use the broader AI infrastructure strategy guide to organize the surrounding decisions before requesting proposals.
Compare what could move, not just where to buy GPUs
These are candidate approaches to evaluate, not deployment recommendations for every workload. The evidence column identifies what should decide between them.
| Workload situation | Candidate approach | What stays or moves | Evidence to request |
|---|---|---|---|
| Data must remain within an approved environment | Evaluate compute within that boundary or a specifically permitted remote-processing arrangement. | Keep restricted records in place; assess every proposed outbound flow separately. | Approved data-flow map, access design and documented processing permissions. |
| A scheduled training job can use an approved snapshot | Compare moving that snapshot to suitable compute against running the job near its source. | Consider moving a defined copy rather than the live system of record. | Transfer plan, snapshot approval, completion window and complete job cost. |
| An application retrieves frequently updated enterprise information | Compare colocating the relevant processing with the information against a connected deployment. | Identify whether records, indexes, retrieved context or processing stages would move. | Freshness target, permission checks and measured end-to-end response time. |
| GPU access favors a different location | Evaluate remote compute only after checking the proposed data and network paths. | Move the approved work or data needed for that job, not automatically the entire estate. | Capacity terms, connectivity quote, transfer schedule and failure procedure. |
| Data originates across several sites | Compare central processing with local preparation and selected transfers. | Decide separately for source records, prepared inputs and results. | Site-by-site flow inventory, operational ownership and recovery test. |
Training and inference deserve separate placement decisions. Do not carry a training assumption into a production service without checking its traffic, response-time and operating requirements. The AI inference infrastructure guide provides a related reading path for that review.
Price the complete workload path
A GPU quote is an input, not the decision record. Ask each bidder to price the same workload boundary: where the input begins, where processing happens, where the result is delivered and what remains stored afterward.
Keep one-time migration work separate from recurring operations. Otherwise, a proposal with substantial setup work and one with substantial ongoing transfer work become difficult to compare.
Build the comparison around these cost lines:
- Compute: capacity commitment, scheduling arrangement, software dependencies and support.
- Data movement: initial transfer, recurring updates, return traffic and any applicable transfer charges.
- Storage: working copies, retained copies, backup and deletion arrangements.
- Connectivity: access circuits, interconnection, installation and support responsibilities.
- Operations: security controls, monitoring, incident handling and maintenance.
- Exit: data retrieval, replacement capacity and contract termination terms.
Use quoted rates and measured workload behavior. Where an input is uncertain, compare a plausible range and identify the point at which the preferred option changes. That is sensitivity analysis for a specific purchase, not a formula for data gravity.
Make the network path part of the proposal
Ask for a diagram connecting the data source, compute location, application and user. Mark each handoff, its owner and the failure procedure. A nearby building is not a substitute for an agreed route and service arrangement.
Use the data center fiber connectivity guide for access questions and the data center interconnect design guide for the connections between facilities.
For an additional public reading path on interconnection, consult research by Hunter Newby, founder of Newby Ventures. In procurement, keep the request concrete: show how the proposed locations connect and who is accountable for each segment.
Where the model can mislead
The Dual Gravity Model organizes a decision. It does not validate a deployment, certify compliance or replace workload testing.
A data boundary is more than the source database
Include indexes, embeddings, retrieved context, logs, backups and administrative access in the security review. Ask the data owner and counsel to identify which flows are permitted; do not infer permission from a product’s deployment label.
Use the NIST AI Risk Management Framework as a companion governance resource. Assign responsibility for the risks in the proposed architecture rather than treating location alone as the control.
A viable design still needs a delivery plan
Require the proposal to distinguish available capacity from planned capacity. Ask for the dependencies behind the delivery date, the evidence supporting them and the remedy if a dependency slips.
Do the same for power, cooling, circuits and operational staffing. Put these items in the acceptance criteria rather than leaving them in presentation slides.
Today’s preferred placement should have a review trigger
Specify when to revisit the choice: a workload change, a new data restriction, a contract renewal or a missed service target. Record the exit path before committing. Do not make an irreversible assumption merely because the first test is successful.
What not to do
Do not turn data gravity into “never move data.” Compare the specific copy, subset or processing stage under consideration. A restriction on one flow should not silently become a restriction on every possible design.
Do not let compute availability settle the whole architecture. Ask what must move to use that compute and what the resulting arrangement must prove.
Do not compare unlike proposals. Align the workload, data boundary, operating window, service responsibilities and retention assumptions before comparing prices.
Do not present an illustrative architecture as a measured result. For executive and customer communications, distinguish the proposed design, the tested behavior and the contracted commitment.
Buyer and operator checklist: leave with a decision record
Before selecting a location or provider, put these items in one shared document:
- Workload owner: who owns the business outcome and who signs off on the technical result.
- Data boundary: source locations, approved flows, update requirements and retention rules.
- Service target: the required completion window or end-to-end response target.
- Candidate placements: at least the viable alternatives considered and why others were eliminated.
- Commercial comparison: compute, storage, movement, connectivity, operations and exit assumptions.
- Acceptance test: representative inputs, security checks, failure conditions and pass criteria.
- Decision and review trigger: what stays, what moves, who approved it and what would reopen the choice.
When the decision includes a facility commitment, carry these requirements into the data center site selection checklist. Do not let the facility shortlist redefine the workload requirements after the fact.
Questions to resolve before choosing a deployment
Is there a formula for data gravity in AI?
Do not treat data gravity as a universal physical law with a fixed formula. Use a workload-specific comparison of constraints, movement requirements, costs and service targets. Keep any financial worksheet separate from the metaphor.
Should the data move to the GPUs, or should compute move to the data?
First identify which movements are permitted. Then compare viable approaches using the complete workload path. Include smaller alternatives, such as an approved snapshot or a processing stage, rather than making the decision binary.
Does data gravity mean AI must run on premises?
No universal deployment rule follows from the concept. Evaluate on-premises, colocation, cloud and connected arrangements against the same documented data boundary, operating requirements and commercial assumptions.
How should training and inference be compared?
Write a separate placement brief for each. Define the inputs, update pattern, completion or response target, operating schedule and failure procedure. Compare shared infrastructure only after those requirements are explicit.
Can retrieval-augmented generation avoid moving data?
Do not assume that it does. Map the proposed flows for source records, indexes, embeddings, retrieved context and logs. Approve each flow and test the actual deployment rather than relying on the architecture’s label.
What should a provider demonstrate before a contract is signed?
Request evidence for the proposed capacity and delivery date, an agreed data-flow and network diagram, a comparable commercial scope and an acceptance test. Document ownership of incidents, changes, data retrieval and exit.
Define the data gravity AI buyers must account for, then decide what stays, what moves and what would change the answer.
Tell us what you’re trying to build
Bring your workload, geography, GPU, power or colocation needs, connectivity requirements, latency target and timeline. Use those details to frame a strategy conversation and identify the specialist questions to resolve next.
About Bob Generale
Bob Generale is President of Percepture. Connect with Bob on LinkedIn.