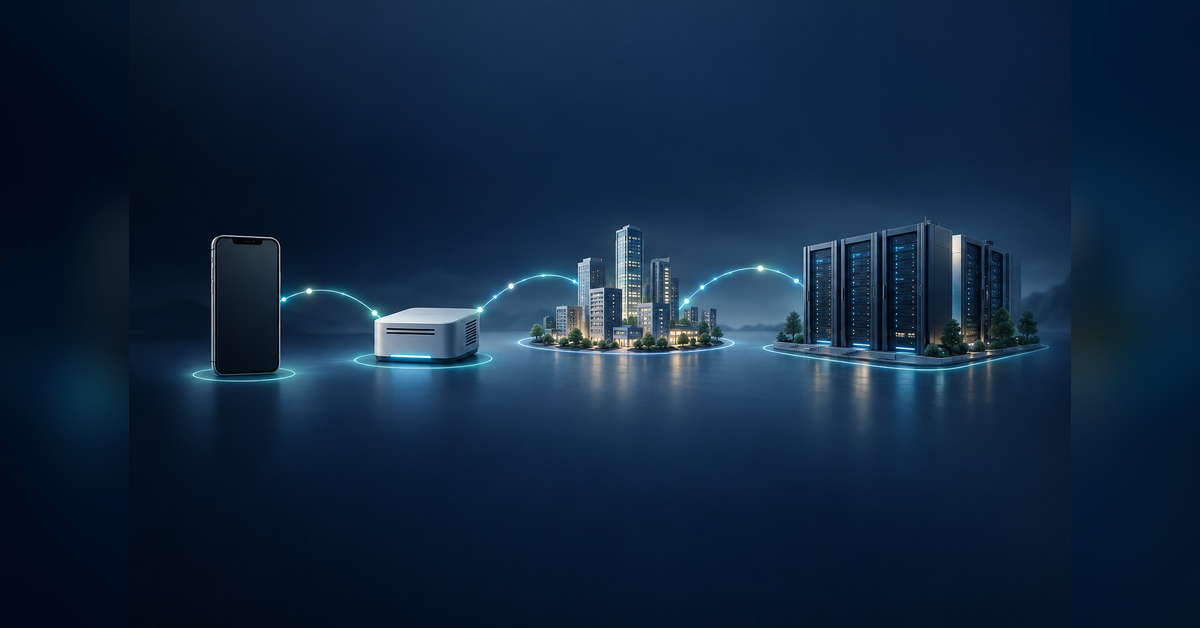

On-device vs edge vs cloud AI inference is a workload-placement decision, not a contest between building types. Compare the device, gateway, metro edge, regional data center, and cloud against model quality, response time, data handling, and cost. A phone running a model is an endpoint, not an edge data center.
This guide is for owners, CEOs, CMOs, and infrastructure teams evaluating an AI-enabled product or service. Use it to turn an “edge AI” pitch into a placement decision with explicit acceptance tests, operating ownership, and fallback behavior.
What do device, edge, and cloud mean here?
Use these working definitions to keep the buying conversation precise:
- Device: the model executes on the phone, computer, camera, or other endpoint itself.
- Gateway: the model executes on a shared local system serving nearby endpoints.
- Metro edge: evaluate shared infrastructure serving the target metropolitan market, with its actual network path specified.
- Regional data center: evaluate a regional compute location, including how applications and data reach it.
- Cloud: evaluate the provider-managed execution service and identify its actual serving location.
Record physical placement and service model separately. Do not use “cloud” or “edge” as a substitute for an architecture diagram.
Use the Inference Placement Hierarchy to narrow the shortlist
Device → gateway → metro edge → regional data center → cloud
Percepture’s Inference Placement Hierarchy is a sequence of questions, not a ranking from best to worst. Begin at the endpoint and ask what prevents the workload from running there. Carry that constraint to the next placement rather than assuming every workload belongs closer to the user.
“The edge isn’t a building. It’s the closest place the workload can run without breaking the economics or the experience.”
Bob Generale, President of Percepture
At each step, apply four gates: acceptable output, acceptable response time, acceptable data handling, and an operating model you can support. Eliminate placements that fail a hard requirement. Compare the remaining options on total cost, resilience, and responsibility.
A documented constraint can remove a placement before a pilot. If a candidate cannot support the required model or an approved data boundary, there is no reason to test it merely to complete the hierarchy.
For the wider planning context, connect this placement decision to your AI infrastructure strategy. If the network requirements are still undefined, use the data center fiber connectivity guide to frame the questions you take to providers.
Compare placements by what must be proven
Use this table to build a shortlist. Each row identifies a candidate and the evidence to request, not a promised performance level.
| Placement | Consider first when | Evidence to request | Reject or redesign when |
|---|---|---|---|
| Device | The feature needs a local execution path or must meet a defined offline requirement. | Task-quality results on supported devices; sustained response time; memory, battery, and update tests. | The supported device fleet cannot pass the required quality or operating tests. |
| Gateway | Several endpoints need a shared local execution point and someone can own it. | Concurrent-load tests; local network behavior; replacement, patching, and failover procedures. | Local support, shared capacity, or recovery arrangements do not meet the service requirement. |
| Metro edge | A market-specific deployment is a plausible answer to the workload’s response-time or location requirements. | Measurements from actual user networks; serving location; interconnection path; capacity and failure tests. | The measured service misses the target or its geographic footprint leaves important users uncovered. |
| Regional data center | A regional deployment is a candidate for pooling the workload under a defined infrastructure operating model. | Application-to-site measurements; capacity plan; power and cooling requirements; network and recovery design. | Required capacity, connectivity, operations, or recovery cannot be secured on the project timeline. |
| Cloud service | You want to evaluate a managed inference service against the required model, deployment scope, and commercial terms. | Model and region availability; quotas; loaded response times; data terms; billing assumptions; exit plan. | The service cannot meet a hard requirement or the contract leaves an unacceptable dependency unresolved. |
Do not award a placement points simply for being “local,” “distributed,” or “managed.” Ask which requirement it satisfies and which new obligation it introduces.
Make the decision with a workload test, not a location claim
Alex Mannine, AI and Technical Automation Strategist, offers a useful starting observation: “Some inference will come from personal phones.” Treat that as a reason to include the endpoint in the shortlist, not as a recommendation to put every model on a phone.
Define a successful task before comparing infrastructure
Write down the input, expected output, acceptable error, response deadline, and action taken after the result. For an interactive feature, specify when the user needs the first useful response and when the task must finish. For a batch workflow, specify the completion window.
Marketing leaders should translate the intended customer experience into acceptance criteria. “Responsive” is not a procurement requirement. Describe what the customer must be able to do, under which conditions, and what happens when the feature is unavailable.
Compare candidates under equivalent conditions
Use the same representative task set and acceptance rubric. Keep model versions, output requirements, and load assumptions comparable. If a smaller local model competes with a different hosted model, report that as a system comparison, not a hardware-only comparison.
Measure the complete application path. Ask the team to separate transport, waiting, model execution, retrieval, and tool calls where relevant. Request typical and slow-tail results, including a high-percentile measure such as p95, rather than accepting one average.
Our guide to low-latency networking for AI is a related resource for the network portion. Keep network measurements separate from the model’s own execution measurements.
Test the conditions that could overturn the choice
Include representative concurrent demand, interrupted connectivity, dependency failures, and sustained operation. For device candidates, test the supported hardware range. For shared infrastructure, test contention and recovery. For a managed service, test the limits and behavior relevant to your contract.
Keep a decision record: candidates, assumptions, measurements, rejected options, accountable owner, and reconsideration triggers. That record should explain why the placement fits this workload, not why a technology category is universally superior.
The risks a placement label does not resolve
Data control and security
Do not approve a design solely because someone calls it local or private. Map inputs, outputs, logs, telemetry, retrieval sources, and backups. Ask where each is processed, who can access it, how long it is retained, and whether fallback changes the approved boundary.
Have the responsible security, privacy, and legal teams evaluate those data flows against your requirements. Keep contractual commitments attached to the actual service and configuration.
Cost and operating ownership
Build a cost worksheet that includes hardware or service charges, software, network transport, storage, deployment, support, and recovery. Include replacement and exit costs where relevant. Compare cost per task that meets the acceptance standard, not just a unit price detached from output quality.
Assign an owner for model updates, endpoint compatibility, monitoring, incidents, and rollback. Ask who performs each job and how it is funded. Do not leave those responsibilities in the gap between the application team and the infrastructure supplier.
Location, connectivity, and resilience
Do not infer an application’s network experience from a map pin. Request measurements from the access networks and markets the service will actually serve. For deployments spanning facilities, review the data center interconnect design guide alongside the placement brief.
Document the response to a lost device, unavailable gateway, interrupted connection, or unavailable service. Decide whether the application stops, queues work, degrades, or uses another placement. Test that behavior against both the customer experience and the approved data boundary.
What not to do
- Do not rename a phone an edge data center. Describe it as an on-device inference endpoint and specify what executes there.
- Do not buy “edge” without an execution boundary. Ask for the model location, supporting dependencies, network path, and accountable operator.
- Do not choose between cloud and data centers as if those labels describe the same dimension. Record the physical location separately from the service and ownership arrangement.
- Do not turn an advertised latency number into a workload guarantee. Require a defined task, measurement boundary, load, geography, and acceptance threshold.
- Do not call fallback harmless. Apply the same quality, data-handling, and customer-experience review to the fallback path.
For terminology reference, consult AWS’s edge inference overview and Arm’s edge AI material. In a buying conversation, follow every category label with a request for the specific execution design.
The workload brief to take into a vendor meeting
Prepare one shared brief before requesting quotes. Require competing proposals to answer the same questions.
- Task and quality: name the use case, representative inputs, output standard, and decision owner.
- Experience target: define the response deadline, demand pattern, concurrency, and acceptable degraded behavior.
- Placement and geography: identify users, supported devices, candidate locations, and required data boundaries.
- Dependencies: list retrieval, tools, storage, gateways, connectivity, and any service required to complete the task.
- Infrastructure: ask the provider to specify GPU or other compute requirements, power, cooling, colocation, fiber, and interconnection where applicable.
- Operations and economics: assign deployment, patching, monitoring, recovery, support, and budget responsibilities.
- Acceptance and timeline: agree on the test set, pass criteria, delivery dependencies, decision date, and exit conditions.
Finish with a decision sentence: “We propose this placement for this workload because it meets these requirements; we will reconsider it if these conditions change.” If the team cannot complete that sentence, return to the unresolved requirement before selecting a supplier.
Questions to resolve before selecting a placement
Does a phone running an LLM count as an edge data center?
No. In this guide, it is an on-device inference endpoint. Specify which model executes on the phone and which supporting functions, if any, depend on another system.
Do we need a gateway between devices and shared infrastructure?
Do not add one simply to fill a step in the hierarchy. Evaluate a gateway when you have a defined local sharing or control requirement, and assign responsibility for its capacity, updates, and recovery.
How should we compare latency claims?
Require the same task, output standard, load, measurement boundary, and user geography. Ask for both typical and slow-tail results, and distinguish model execution from the complete application response.
Which placement is cheapest?
Build a workload-specific comparison rather than selecting by category. Include compute, network, software, operations, resilience, and exit costs, then compare the cost of tasks that meet your acceptance standard.
How should we evaluate a hybrid design?
Define which tasks execute at each placement and what triggers a handoff. Apply acceptance tests to the combined path, including failures, data movement, and the user experience during fallback.
When should we revisit the placement decision?
Set review triggers in the decision record. Examples include a changed model, a new device fleet, expansion into another market, a revised data policy, sustained demand changes, or a material contract change.
The useful output of an on-device vs edge vs cloud AI inference comparison is a workload brief, a shortlist of viable placements, and a test plan. Choose among options that pass your requirements, then document when to reconsider the decision.
Tell us what you’re trying to build
Bring your workload, geography, infrastructure requirements, latency target, and timeline. Use the conversation to discuss fit, unresolved requirements, and an appropriate next step.
About Bob Generale
Bob Generale is President of Percepture.