
Tracking AI visibility requires more than searching for your company name once. A useful review of Perplexity brand mentions examines whether the brand appears, how it is described, which pages are cited and whether the answer recommends it for a relevant need.
The goal is not to manufacture a single ranking. It is to build a repeatable view of how the brand appears across the questions buyers ask, then use that evidence to guide content, authority and measurement decisions.
What should a Perplexity visibility review measure?
A review of Perplexity brand mentions should track four separate signals: brand inclusion, the context of the mention, cited source pages and recommendation language. Run the same prompt set on a schedule, save the answer and citations, and compare changes by topic rather than relying on one isolated response.
The executive view
- Measure prompts, not just keywords: Buyers ask full questions with industries, problems and constraints.
- Separate visibility signals: A mention, citation and recommendation are not the same result.
- Keep the test stable: Consistent prompts and records make Perplexity brand mentions easier to compare over time.
- Prioritize source gaps: Identify which owned or third-party pages appear behind useful answers.
Why does this visibility matter?
A traditional rank report tells you where a page appeared for a defined query. An AI answer can combine several sources, mention multiple companies and frame each company differently. That makes Perplexity brand mentions useful as a research signal, but only when the review preserves the question, answer, citations and context.
For a business leader, the central question is not simply, “Did our name appear?” It is, “Did we appear in the buying situations that matter, and was the description accurate and useful?” A brand can be visible for an informational question yet absent from a comparison, shortlist or recommendation prompt.
This is also why AI search visibility should not be reported as one unexplained score. Leadership needs to see the topics tested, the prompts behind the result and the source pages connected to each answer.
What should you track?
A sound measurement model keeps distinct outcomes separate. Combining them can make a weak result look stronger than it is.
| Signal | What to record | Why it matters |
|---|---|---|
| Brand inclusion | Whether the brand appears in the answer | Shows basic visibility for the tested prompt |
| Mention context | The words and category used around the brand | Reveals how the answer frames the company |
| Owned citation | The exact company page cited | Connects the answer to a source the company controls |
| Third-party citation | The publication, directory or other external page cited | Shows which outside sources shape the answer |
| Recommendation | Whether the brand is presented as a possible choice | Separates discovery from buyer-oriented visibility |
| Competitor inclusion | Other organizations named for the same prompt | Adds context without turning the review into a vanity score |
This structure turns Perplexity brand mentions into auditable observations. It also prevents a cited page from being reported as a recommendation when the answer only used that page as background.
How do you build a repeatable tracking process?
1. Define the buying situations
Start with the problems, comparisons and decisions that can lead a qualified buyer toward your category. Group them by intent: learning, evaluating approaches, comparing providers and selecting a partner.
A useful baseline for Perplexity brand mentions includes prompts where the brand should reasonably appear. Do not inflate the test with unrelated questions just to create a larger dashboard.
2. Build a stable prompt set
Create prompts that reflect natural buyer language. Include broad category questions, problem-led questions, comparison questions and prompts with meaningful constraints such as industry, location, company size or required capability.
Each prompt should test one clear situation. Keep a stable core set for trend analysis, while maintaining a smaller exploration set for new questions. This balance lets Perplexity brand mentions remain comparable without freezing the program around yesterday’s market language.
Prompt records should include:
- The exact question
- The intent and topic cluster
- The audience or buyer role
- The date of the review
- The answer text or approved capture
- Every visible citation URL
- Mention and recommendation status
- Notes about wording or source changes
3. Capture the complete answer
A yes-or-no mention field is not enough. When collecting Perplexity brand mentions, preserve the surrounding sentence and the sources attached to the response. The context shows whether the brand was described accurately, placed in the right category or merely referenced in passing.
Use the same review method each time. If the testing conditions change, record the change instead of presenting the new result as a clean continuation of the old series.
4. Classify the source gap
For each important prompt, ask why the answer may have selected its sources. Review whether your site has a focused page that answers the question, whether the page makes the entity and offer clear, and whether credible third-party coverage exists around the topic.
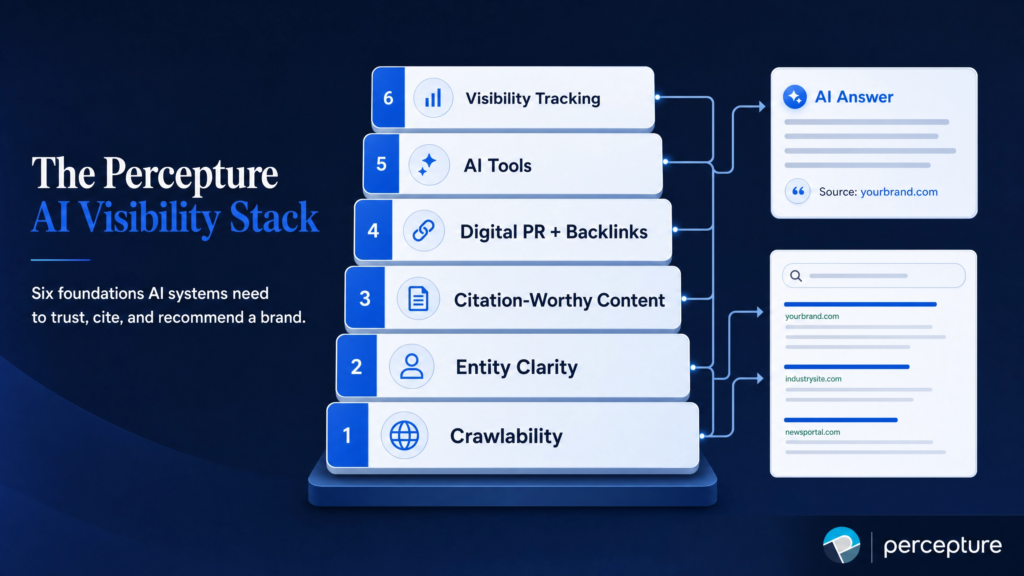
This is where tracking connects to action. Percepture’s guide to an AI content citation strategy explains how source-ready content fits into broader visibility work. The tracking sheet identifies the gap; editorial, technical and authority work address it.
How should success be scored?
An AI visibility scorecard that leaders can audit
Score Perplexity brand mentions at the prompt level before rolling them into topic-level reporting. Keep the raw observations beside any summary score.
| Review question | Record as |
|---|---|
| Was the brand included? | Yes or no |
| Was the brand described in the intended category? | Aligned, mixed or misaligned |
| Was an owned page cited? | Exact URL or none |
| Was the brand recommended? | Recommended, mentioned or absent |
| Did the answer cite a relevant third party? | Exact URL or none |
| Did the result change from the prior review? | Improved, unchanged, declined or not comparable |
The scorecard should not hide the sample behind a percentage. Report how many prompts were tested, which intent groups they represent and which prompts changed. That gives decision-makers enough context to judge whether movement is broad or tied to one answer.
How should you interpret changes?
Treat movement in Perplexity brand mentions as a diagnostic signal rather than automatic proof of business impact. A newly cited owned page can point to stronger source visibility. A new recommendation can indicate better alignment for that prompt. Neither observation proves revenue or lead quality by itself.
Look for patterns across a topic cluster. If several related prompts begin citing the same page, review what that page explains clearly. If the brand disappears from several comparison prompts, inspect competitor sources, category language and gaps in your own coverage.
The most useful review connects AI visibility to other evidence. Percepture’s attribution and analytics service addresses the separate job of connecting marketing activity to business outcomes.
What actions can improve the underlying signal?
Use the findings to prioritize work, not to chase every answer variation. Perplexity brand mentions may reveal that the site lacks a direct category explanation, a comparison page, clear organizational details or a source-worthy answer to a recurring buyer question.
The response should match the gap:
- Improve unclear pages instead of publishing a duplicate.
- Create a focused resource when no existing page satisfies the intent.
- Strengthen entity details and service language where ambiguity exists.
- Support factual claims with accessible evidence.
- Pursue relevant third-party coverage when outside validation is missing.
- Re-run the stable prompt set after meaningful changes have had time to be discovered.
Organizations that need coordinated research, content and authority work can evaluate Percepture’s generative engine optimization services as one path from diagnosis to execution.
Which tracking mistakes create misleading reports?
The first mistake is treating one answer as a fixed ranking. Perplexity brand mentions should be reviewed across a planned prompt set, not reduced to a screenshot from a favorable question.
The second mistake is counting citations and recommendations as the same event. A page can support an answer without the company being presented as a choice.
The third mistake is changing prompts between reviews without marking the series as different. Small wording changes can alter the buyer situation being tested, so comparisons need a stable core.
The fourth mistake is using a tool score without retaining the prompts and source URLs behind it. A tool can accelerate collection, but the buyer still needs transparent records. A supplied Perplexity rank tracker roundup can help teams form a shortlist; each product should still be evaluated against the workflow, export and audit requirements in this guide.
The final mistake is reporting visibility as revenue. Keep AI-answer observations, site engagement and pipeline evidence in their proper layers.
When should you use manual reviews or a platform?
Choose the method that matches the program
| Method | Best fit | Watch for |
|---|---|---|
| Manual review | A small, high-value prompt set or an early baseline | Inconsistent capture and limited scale |
| Tracking platform | Recurring reviews across many topics, markets or competitors | Opaque scores and weak access to raw answers |
| Hybrid process | Automated collection with human review of priority prompts | Unclear ownership between data collection and interpretation |
Regardless of method, Perplexity brand mentions need a retained prompt, answer, source record and classification rule. The software should support the method rather than define it.
What should leadership receive each month?
A concise report should show topic-level visibility, recommendation coverage, owned citations, third-party sources, material changes and the actions assigned to each gap. It should also disclose the prompt set and review period.
For Perplexity brand mentions, include examples that explain movement rather than selecting only the strongest answers. One aligned mention, one source gap and one changed result often teach more than a crowded chart.
End with decisions: which existing page needs revision, which missing question deserves a new resource, which source relationship matters and which prompts will be retested. That keeps the report tied to work the team can control.
Turn visibility tracking into a decision system
Treat Perplexity brand mentions as structured market observations: define the prompts, preserve the sources, classify each result and connect gaps to specific work. The value comes from disciplined comparison and better decisions, not from claiming a permanent AI ranking.
Build an AI visibility measurement plan
Percepture can help your team define the prompt set, source review and reporting structure behind a practical GEO program.
About Bob Generale
Bob Generale is President of Percepture. He works with business and marketing leaders on digital strategy, search visibility and integrated growth programs. Connect with Bob on LinkedIn.